LangDriveCTRL: Natural Language Controllable Driving Scene Editing with Multi-modal Agents

Yun He1 Francesco Pittaluga2 Ziyu Jiang2 Matthias Zwicker1
Manmohan Chandraker2,3 Zaid Tasneem2

1University of Maryland, College Park    2NEC Labs America    3UC San Diego

ECCV 2026

Editing Results

Insert a blue sedan 3 meters to the left of ego vehicle, 7 meters ahead that will change to the right lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Insert a black sedan 4 meters to the left of ego vehicle, 9 meters ahead, and make it change to the right lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Add a red sedan 8 meters in front of ego vehicle and make it change to the middle lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Delete the white vehicle on the left.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Remove the white sedan.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Remove the vehicle directly ahead.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Change the white sedan on the right to a dark blue sedan.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Change the black sedan on the right to a blue sedan.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Replace the black SUV with a white sedan.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Make the ego vehicle change to the rightmost lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Make both the silver vehicle and the ego vehicle change to the middle lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Have the black SUV on the right change to its left lane.
0%

Input

0%

ChatSim

0%

Cosmos

0%

Ours

Make the white SUV on the opposite left lane speed up and turn left
0%

Input

0%

Ours

Make the gray SUV ahead turn left and the gray mini-van on the oncoming left lane go straight
0%

Input

0%

Ours

Method Comparison

ChatSim Agent-Based Method
✗ Photorealism
✗ Instruction Alignment
✓ Structure Preservation
✗ Traffic Realism
Cosmos Diffusion-Based Method
✓ Photorealism
✗ Instruction Alignment
✗ Structure Preservation
✓ Traffic Realism
Ours Agentic Workflow + Diffusion
✓ Photorealism
✓ Instruction Alignment
✓ Structure Preservation
✓ Traffic Realism

Abstract

LangDriveCTRL is a natural-language-controllable framework for editing real-world driving videos to synthesize diverse traffic scenarios. It represents each video as an explicit 3D scene graph, decomposing the scene into a static background and dynamic object nodes. To enable fine-grained editing and realism, it introduces a feedback-driven agentic pipeline. An Orchestrator converts user instructions into executable graphs that coordinate specialized multi-modal agents and tools. An Object Grounding Agent aligns free-form text with target object nodes in the scene graph; a Behavior Editing Agent generates multi-object trajectories from language instructions; and a Behavior Reviewer Agent iteratively reviews and refines the generated trajectories. The edited scene graph is rendered and harmonized using a video diffusion tool, and then further refined by a Video Reviewer Agent to ensure photorealism and appearance alignment. LangDriveCTRL supports both object node editing (removal, insertion, and replacement) and multi-object behavior editing from natural-language instructions. Quantitatively, it achieves nearly 2× higher instruction alignment than the previous SoTA, with superior photorealism, structural preservation, and traffic realism.

Pipeline

Method Pipeline

Overall Pipeline. Given an input video and the user instruction, our pipeline first builds a scene graph, which decomposes the scene into a static background node and multiple dynamic object nodes with their trajectories. To execute the instruction, the orchestrator coordinates agents and tools from different modules to work together: the object query module localizes target objects in the scene graph based on textual descriptions; the object node editing module performs object removal, insertion, and replacement; the behavior editing module generates and refines multi-object trajectories based on a feedback loop; finally, the rendering and refinement module renders the edited scene graph and iteratively refines it with a video diffusion tool. While the figure illustrates single-object editing, our pipeline is capable of multi-object editing.
Reviewer Agents

The Behavior Reviewer refines the generated trajectories, the Video Reviewer refines the rendered result — both correct in a closed loop.

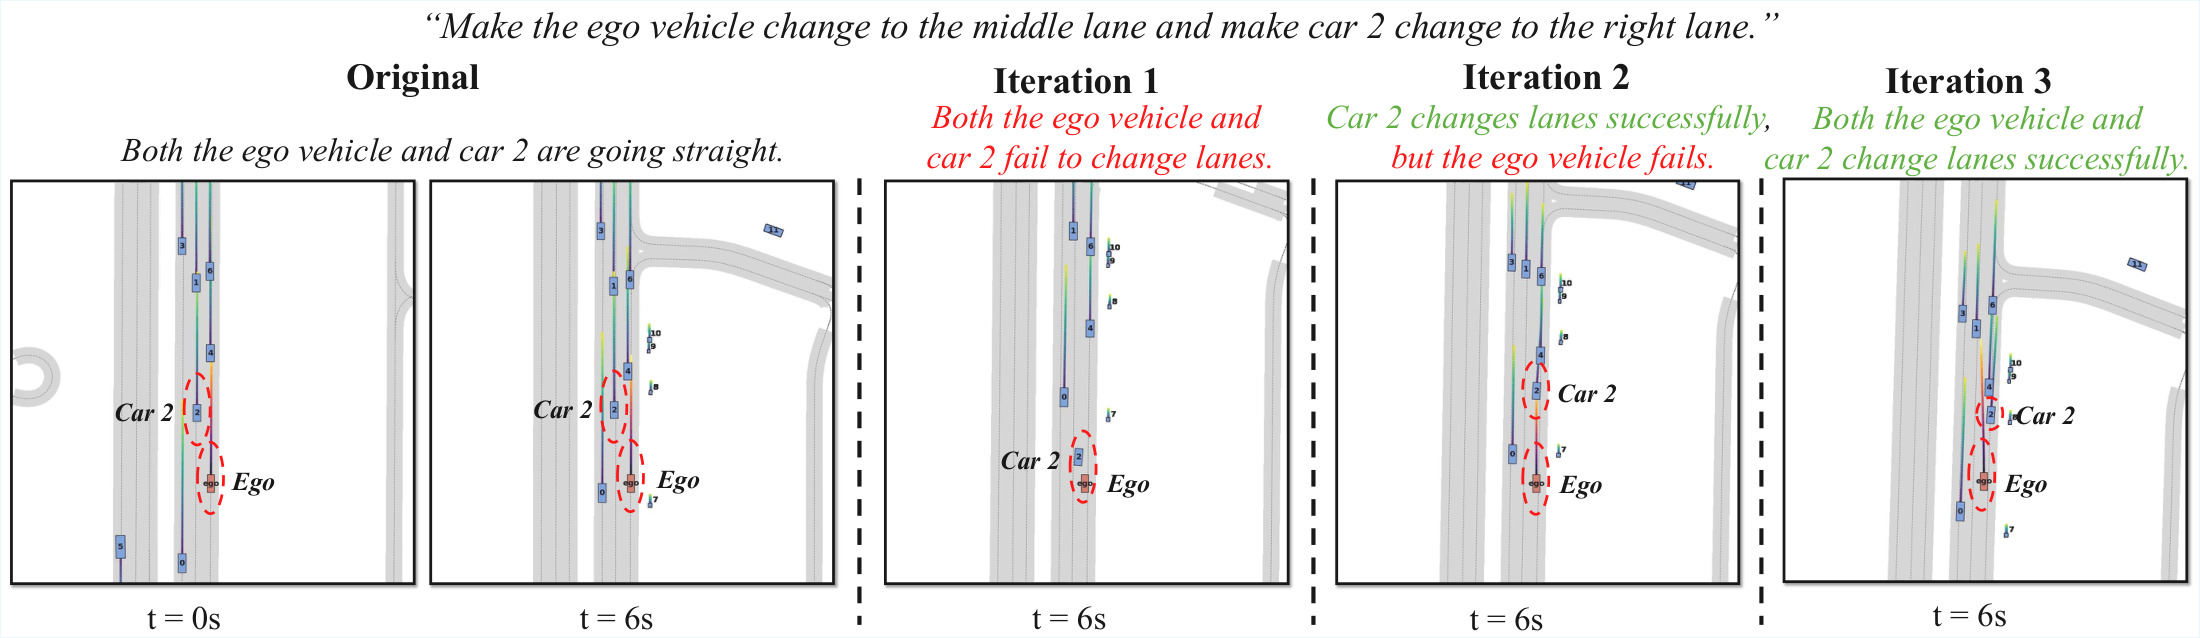
Behavior Reviewer Agent

Behavior Reviewer Agent feedback loop
Trajectory success 34%→51% Off-road 30%→14%

Behavior Reviewer Agent. After the behavior editing agent generates multi-object trajectories, the Behavior Reviewer inspects them against the instruction and reports which maneuvers failed. The behavior editing agent regenerates from that feedback, and the loop repeats until every target maneuver is executed correctly.

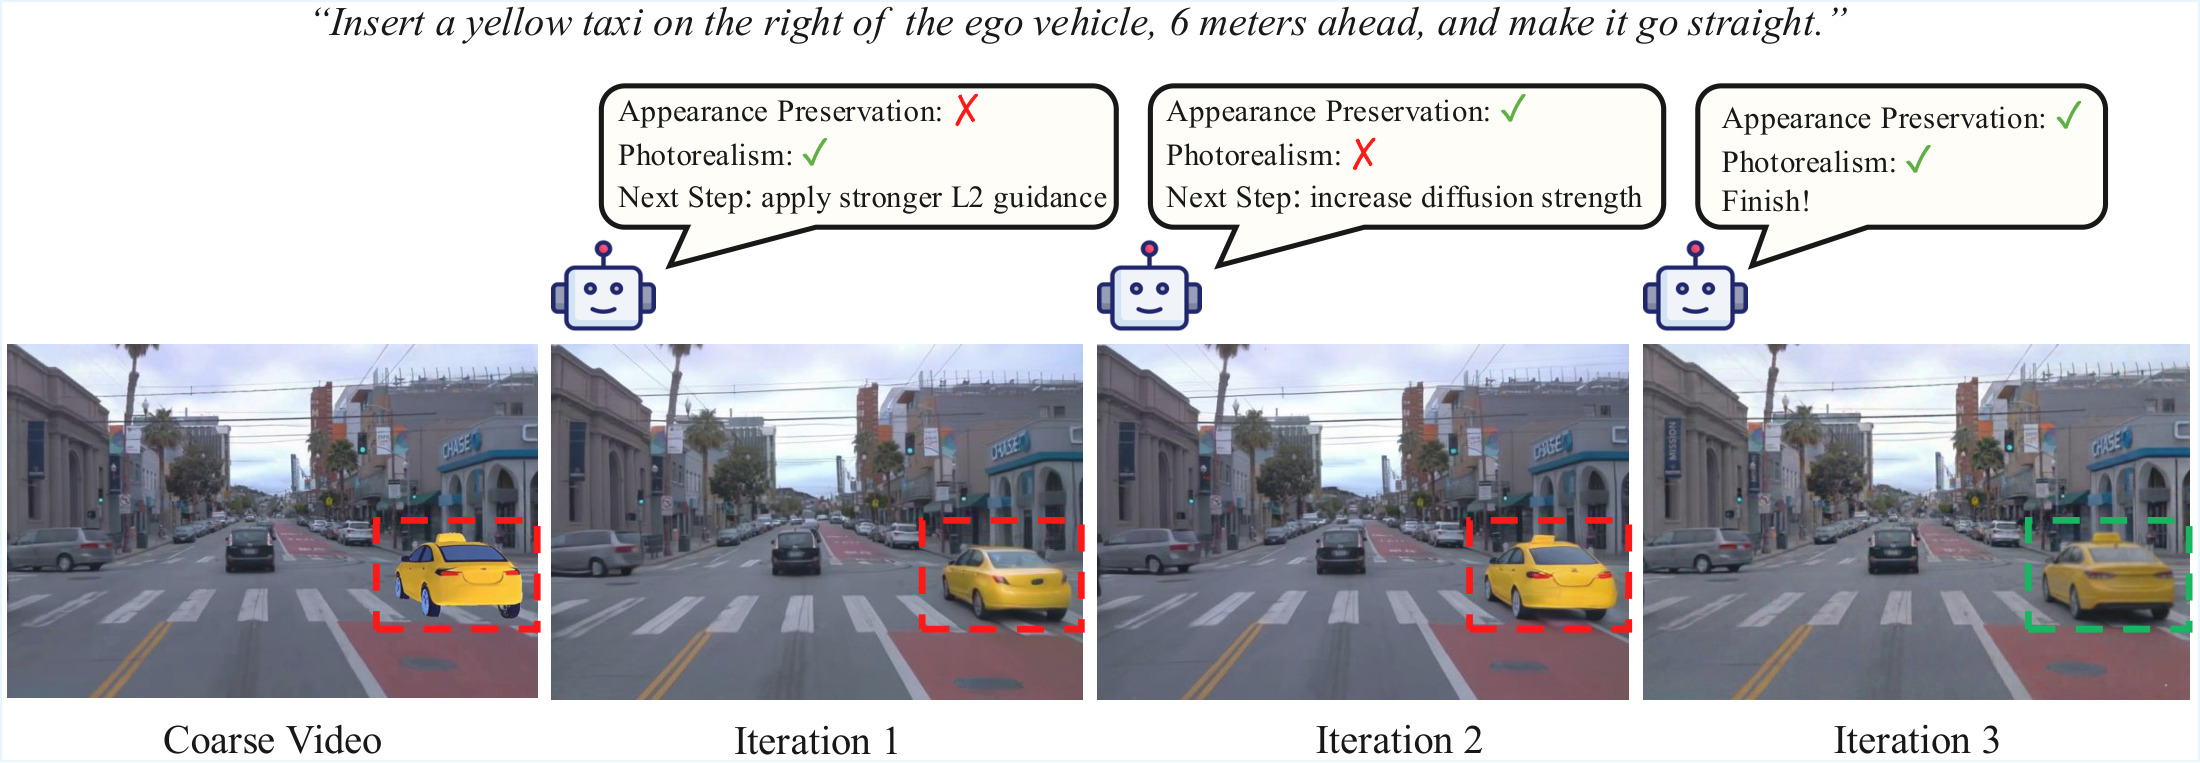
Video Reviewer Agent

Video Reviewer Agent refinement loop
Appearance alignment 65%→85% while improving FID

Video Reviewer Agent. After the video diffusion tool renders the edited scene, the Video Reviewer checks the result for appearance preservation and photorealism. It increases the L2 guidance weight when the appearance drifts and the diffusion strength when the result looks unrealistic, and the loop repeats until both are satisfied.

BibTeX

@article{he2025langdrivectrl, title={LangDriveCTRL: Natural Language Controllable Driving Scene Editing with Multi-modal Agents}, author={He, Yun and Pittaluga, Francesco and Jiang, Ziyu and Zwicker, Matthias and Chandraker, Manmohan and Tasneem, Zaid}, journal={arXiv preprint arXiv:2512.17445}, year={2025} }